

Point us at your GPUs
Kubernetes, bare metal, private cloud, or your own cloud account.
Deploy InferX on your own GPUs, Kubernetes cluster, private cloud, or GPU cloud. Or start with hosted endpoints to try the runtime today.
Reduce inference infrastructure costs by 30-70%* with fast cold starts, higher GPU utilization, isolated workloads, and OpenAI-compatible APIs.
A request enters the OpenAI-compatible API, the scheduler restores initialized model state, GPU capacity attaches while tokens stream, and resources return to the pool when serving completes.
Build vs. Deploy
The simple path
No migration. No new infrastructure to stand up. No engineering sprint.
Kubernetes, bare metal, private cloud, or your own cloud account.
No changes to your existing stack or workloads.
Sub-second cold starts, isolated workloads, live in days.
Prompts, outputs, and API payloads are not stored or used for training.
Requests and responses are protected with modern transport encryption.


SHORTER STARTUP PATH
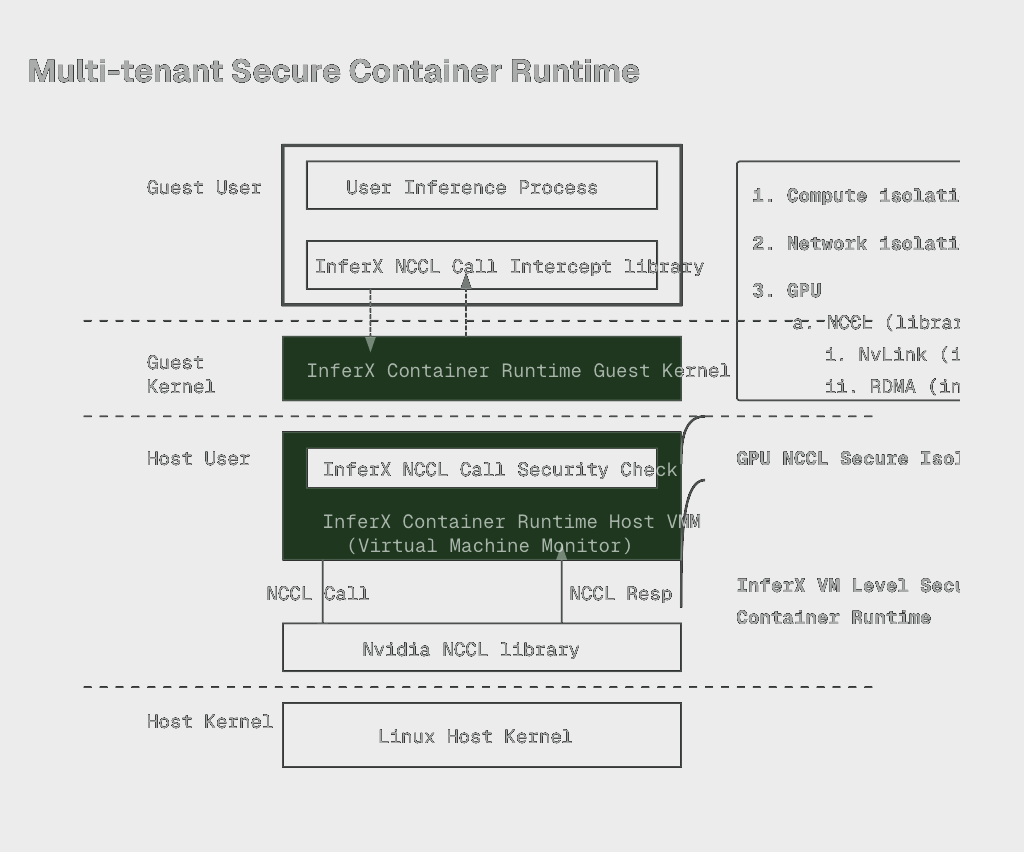
Inside the InferX Runtime
A request enters the OpenAI-compatible API, the scheduler restores initialized model state, GPU capacity attaches while tokens stream, and resources return to the pool when serving completes.
RUNNING ON INFERX ENDPOINTS RIGHT NOW
Same runtime, same snapshot-restore scheduler — hosted for you to test before you deploy it yourself.
OpenAI compatible
Keep the OpenAI Python SDK and request shape. Point your existing client at InferX to serve open models in production.
Verified SDK compatibilityimport osfrom openai import OpenAIclient = OpenAI( api_key=os.environ["OPENAI_API_KEY"], base_url="https://model.inferx.net/v1",)stream = client.chat.completions.create( model="Qwen/Qwen3.6-35B-A3B", messages=[{"role": "user", "content": "Hello, InferX."}], stream=True,)for chunk in stream: print(chunk.choices[0].delta.content or "", end="")