

Point us at your GPUs
Kubernetes, bare metal, private cloud, or your own cloud account.
Deploy InferX Platform on your own GPUs, Kubernetes cluster, private cloud, or GPU cloud. Or access InferX Public Endpoints to try hosted models without managing GPU infrastructure.
Reduce inference infrastructure costs by 30-70%* with fast cold starts, higher GPU utilization, isolated workloads, and OpenAI-compatible APIs.
A request enters the OpenAI-compatible API, the scheduler restores initialized model state, GPU capacity attaches while tokens stream, and resources return to the pool when serving completes.
Build vs. Deploy
The simple path
No migration. No new infrastructure to stand up. No engineering sprint.
Kubernetes, bare metal, private cloud, or your own cloud account.
No changes to your existing stack or workloads.
Sub-second cold starts, isolated workloads, live in days.
SECURITY POSTURE
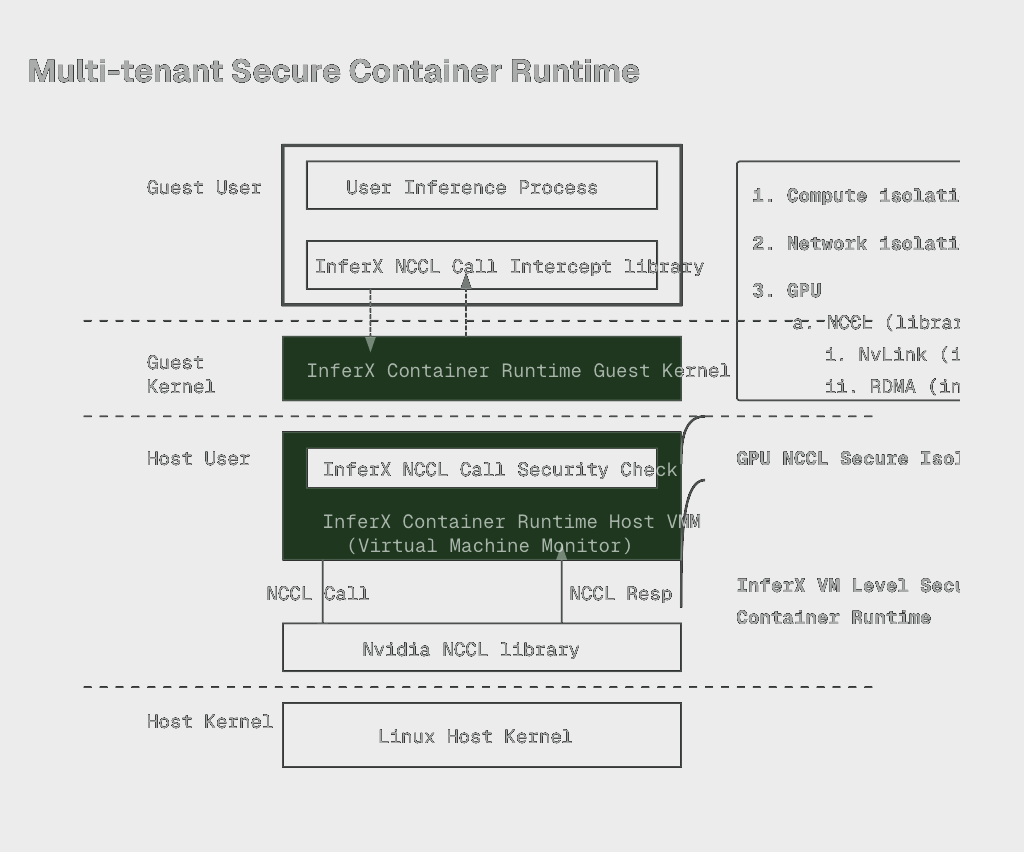
Built for enterprise inference deployments, InferX Platform provides workload isolation, secure execution, and infrastructure-level controls designed to protect customer workloads.
View SecurityDeploy InferX Platform within your infrastructure and maintain control over inference data, access policies, and retention settings.
Requests and responses are protected with modern transport encryption.
SHORTER STARTUP PATH
Inside the InferX Runtime
A request enters the OpenAI-compatible API, the scheduler restores initialized model state, GPU capacity attaches while tokens stream, and resources return to the pool when serving completes.
RUNNING ON INFERX ENDPOINTS RIGHT NOW
Explore hosted model APIs through InferX Public Endpoints, or deploy InferX Platform on your own infrastructure.
OpenAI compatible
Keep the OpenAI Python SDK and request shape. Point your existing client at InferX to serve open models in production.
Verified SDK compatibilityimport osfrom openai import OpenAIclient = OpenAI( api_key=os.environ["OPENAI_API_KEY"], base_url="https://model.inferx.net/v1",)stream = client.chat.completions.create( model="Qwen/Qwen3.6-35B-A3B", messages=[{"role": "user", "content": "Hello, InferX."}], stream=True,)for chunk in stream: print(chunk.choices[0].delta.content or "", end="")